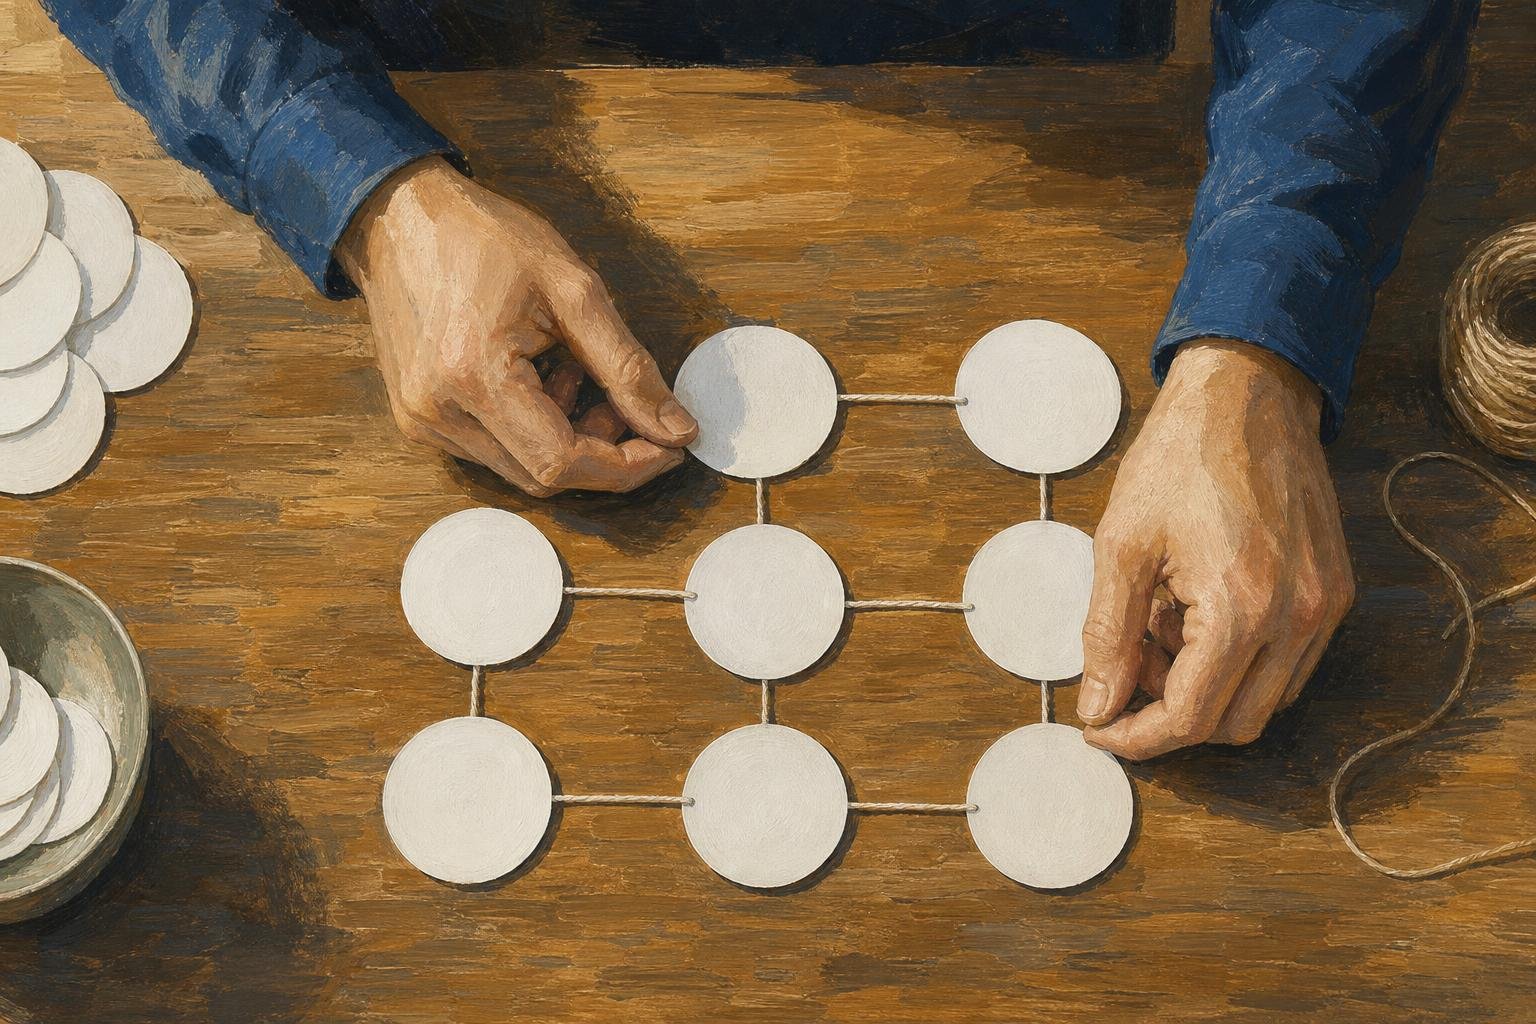

A neural network diagram shows how a model turns inputs into outputs, but an unlabeled output circle can leave an engineer mistaking a score for a probability. Reading or drawing it clearly means making those transformations visible. At each step, identify the data, the operation, and the result.
In This Article
- Read the Arrows and Identify the Layers
- Understand What Happens Inside a Neuron
- Follow a Small Network and Its Shapes
- Match the Drawing to the Architecture
- Draw With Tools That Fit the Job
- Review the Diagram as a Reader
- Key Takeaways
- Frequently Asked Questions
- Start With a Readable Architecture
Read the Arrows and Identify the Layers
Suppose a final circle shows a value without an operation label. Is that a predicted measurement or a class probability? Labeling it “sigmoid: positive-class probability” resolves the ambiguity.
Follow the arrows, usually left to right or top to bottom. Inputs hold supplied features; hidden layers transform them; outputs give predictions or scores. In a fully connected layer, every unit receives values from every unit in the preceding layer. These connections show computational dependencies, not physical wires.
Understand What Happens Inside a Neuron
A typical neuron computes a = φ(Σ wᵢxᵢ + b): incoming values xᵢ are multiplied by weights wᵢ, summed with bias b, then transformed by activation φ. ReLU returns zero for negative inputs and leaves positive inputs unchanged.
The bias is a learned offset, separate from features and weights; show it in the equation or as a labeled constant-value node. That calculation gives the arrows a job.
Follow a Small Network and Its Shapes
A 2–3–1 network has two inputs, three hidden neurons, and one output. Label them x₁ and x₂, h₁ through h₃, and ŷ; draw six input-to-hidden connections and three hidden-to-output connections.
Using column vectors, x is 2 × 1, W₁ is 3 × 2, and b₁ is 3 × 1. Thus h = φ(W₁x + b₁) is 3 × 1. W₂ is 1 × 3, and b₂ has length 1: W₂h + b₂ produces a scalar before output activation.
| Network stage | Example calculation | Result | Output shape | Diagram cue |
|---|---|---|---|---|
| Input layer | Set x₁ = 1 and x₂ = 2 | x = [1, 2]ᵀ | 2 × 1 | Two input nodes hold the feature values |
| Hidden weighted sums | Use W₁ = [[1, 0], [−1, 0], [0, 1]] and b₁ = [0, 0, 0]ᵀ; compute W₁x + b₁ | z₁ = [1, −1, 2]ᵀ | 3 × 1 | Six input-to-hidden edges carry the entries of W₁ |
| Hidden ReLU activation | Apply ReLU(z) = max(0, z) to each hidden weighted sum | h₁ = 1; h₂ = 0; h₃ = 2 | 3 × 1 | Three hidden nodes; ReLU clips the negative sum to zero |
| Output weighted sum | Choose demonstration parameters W₂ = [1, 0, −1] and b₂ = 0; compute W₂h + b₂ | z₂ = 1 × 1 + 0 × 0 − 1 × 2 + 0 = −1 | 1 × 1 | Three hidden-to-output edges feed one output node |
| Sigmoid output activation | For this binary-classification example, apply sigmoid(z₂) = 1/(1 + e^(−z₂)) | ŷ = 1/(1 + e) ≈ 0.269 | 1 × 1 | Label the output “sigmoid: positive-class probability ≈ 0.269” |
Match the Drawing to the Architecture
The example is a multilayer perceptron (MLP). Its circles work because each represents a scalar activation. Now put an attention head inside one circle: the same symbol conceals a computation across tokens. The drawing has changed meaning without warning.
Use blocks for transformer attention and feedforward sublayers, with residual paths bypassing them. Show where positional information enters, including position-dependent attention, and distinguish self-attention from cross-attention when both appear. For a CNN, blocks instead represent feature maps: label spatial dimensions, channel counts, and convolution or pooling operations. RNNs need visible state dependencies. DNN names depth, not an exclusive architecture.
| Network architecture | Best for | Key diagram features | Pros | Cons |
|---|---|---|---|---|
| Feedforward neural network (MLP) | Tabular classification and regression | Input → dense hidden layer(s) → output; arrows move forward only | Direct mapping from fixed-size inputs to predictions; straightforward baseline | No built-in handling of spatial structure or sequence order |
| Deep neural network (DNN; overlapping category) | Learning layered representations for complex prediction tasks | Multiple hidden layers; label the actual layer types, not just “DNN” | Learns hierarchical features; includes deep MLPs, CNNs and transformers | Depth alone does not identify architecture; deeper models can be harder to optimize |
| Convolutional neural network (CNN) | Image classification, object detection and spatial feature extraction | Convolution kernels → feature maps; pooling or strided convolutions for downsampling | Shared kernels reduce parameters versus dense layers on images; captures local patterns | Local kernels need stacked layers or other mechanisms for broad context |
| Recurrent neural network (RNN; includes LSTM/GRU) | Time-series prediction and streaming sequence processing | Recurrent state loop or time-unrolled cells; hidden-state arrows between steps | Carries state across sequence steps; supports incremental processing | Sequential state updates limit training parallelism; basic RNNs struggle with long dependencies |
| Transformer | Language modeling and long-range relationships in token sequences | Attention blocks, feedforward sublayers and residual paths; show positional input or position-dependent attention | Content-dependent interactions across tokens; parallel token processing during training | Standard full attention has quadratic time and attention-memory cost in sequence length |
Draw With Tools That Fit the Job
To draw the worked example in NN-SVG:
- In the FCNN view’s Architecture controls, remove extra populated layers with the minus buttons, leaving three. Set their node counts to 2, 3 and 1.
- Select horizontal direction, enable Show Layer Labels and Show Arrowheads, and keep weight-dependent edge width, opacity and color disabled: the generator’s random weights are not this example’s parameters.
- Select Download SVG. In an SVG editor, label the nodes x₁, x₂, h₁–h₃ and ŷ. Add the table’s weights and biases, mark the hidden layer ReLU, and label the output “sigmoid: positive-class probability ≈ 0.269.”
- Check that all six input-to-hidden and three hidden-to-output connections remain visible, including zero-weight connections.
For a custom residual block in diagrams.net, place an operation rectangle and a labeled addition node. Connect the main path through the operation to the addition; route a second connector around the operation into that same addition.
Place the main path first, then branches. Space comparable layers evenly; pair role colors with text so grayscale remains readable. In diagrams.net, choose File → Export As → SVG, then Export. Inspect the exported labels and connectors at the intended display size.
Review the Diagram as a Reader
At the intended display size, trace an input and check that each operation accepts the preceding output shape. At a merge, addition preserves equal-shaped vectors’ shape; concatenation increases a dimension. A tidy connector can conceal the wrong operation.
Check labels at that same size, since a large editing canvas can hide tiny text. Define abbreviated operations and special line styles in a legend. Mark omitted repetitions explicitly, such as “× 6,” instead of relying on an ellipsis.
Key Takeaways
- Explain computation, not a literal biological brain.
- Follow arrows and track dimensions.
- Define weights and activations.
- Use architectural cues beyond generic neuron stacks.
- Let the drawing’s purpose determine its detail.
Frequently Asked Questions
What Is the Structure of a Neural Network?
Its structure specifies computational units and their connections. If a draft shows layers but hides shared parameters or branches, it leaves out structural information; operations combining intermediate results belong in the drawing too.
Must Every Neuron and Connection Appear in the Drawing?
No, a labeled block can represent a whole layer. If an author wants 1,024 hidden circles, ask what individual circles explain; a 512-unit layer can likewise use representative circles and an explicit count. Draw every edge only when it helps explain the calculation and remains readable.
Does a Connection’s Thickness Always Represent Its Weight?
No; thickness represents weight only when the legend says so. If a collaborator uses width for magnitude, add a separate cue for positive and negative signs: width cannot express both.
How Should Recurrent Connections Be Distinguished From Feedforward Connections?
Use a labeled state loop or unroll the network across time steps. If a loop looks like an ordinary backward arrow, label the state from t − 1 to t and show that recurrent parameters are shared across steps.
When Should You Choose a Schematic Rather Than an Interactive Visualization?
Choose a schematic for a stable explanation readers can print, cite, or compare. Choose an interactive view when changing activations or parameters are the subject, with controls identifying what changes and what stays fixed.
Start With a Readable Architecture
For a first drawing, use the worked network and annotate one hidden neuron before polishing the layout. The arithmetic gives you something concrete to test: the negative hidden sum becomes zero, while the output activation changes a score into a probability. If your task is explaining a larger model, choose blocks and spend the space on dimensions and connections between operations.
Make that choice before choosing software. More circles will not repair an unclear account of what a block does. For the final test, cover the surrounding text and read the figure alone. Can you identify what enters each operation and what leaves it? Any answer that requires guessing marks a missing label, legend entry, or architectural distinction.
Recommended for you
How to Find a Hobby That Truly Fits You
Give a hobby 21 days and 90 minutes per week, and you will learn more about your motivation, stress triggers, and attention than a dozen personality quizzes. A few concrete moves—testing a novel, a 5‑aside game, or a few low-stakes rounds of online gameplay—can reveal which activities calm your nervous system, sharpen focus, and actually […]
Reading as Mental Design: How Books Shape the Way We Think
Flip open a book and you trigger a design studio in your head: eyes fixate for roughly 200–250 ms per word group, 10–15% of eye movements jump backward to verify links, and your working memory holds about four “chunks” while you assemble a model of what the text describes. Reading as a Form of Mental […]
Bubble Chart Accuracy: Why Area Matters More Than Radius
A bubble chart can turn a fourfold rise into a sixteenfold area. Learn to read axes and size, avoid misleading circles, and choose a design. See the guide.
Pareto Chart Priorities: A Clothing-Defect Walkthrough
Read a pareto chart’s bars and cumulative line, calculate category shares, and build one in Excel with a clothing-defect example. See how priorities take shape.
What Is an Infographic? How Visuals Earn Their Place
What is an infographic? See how an electricity chart and appliance diagram can work together to explain a message, not just decorate it. Explore the basics.
Flowchart Examples With Labels You Can Make Your Own
Adapt flowchart examples for online orders, leave requests, and login recovery with named actions, decisions, and outcomes. See reusable paths in the article.
Climate Change Infographic: From Emissions to Action
See how a climate change infographic links heat-trapping gases to rising heat, then separates emissions cuts from adaptation. Explore the causes and actions.
Histogram Patterns: What Clinic Waiting Times Reveal
A histogram turns clinic waiting times into visible clusters and gaps. Learn what bins and bar heights mean, and how to choose bin widths. See the example.